

[Apr 11, 2026] Get to the Top with Workday-Prism-Analytics Practice Exam Questions
Use Real Workday-Prism-Analytics Dumps Free Sample Questions and Practice Test Engine
NEW QUESTION # 29
In a Prism project, you have a dataset containing customer purchase transactions, including the customer ID, purchase amount, and purchase date. You want to analyze the total purchase amount for each customer over the entire period. What transformation stage should you apply to calculate the total purchase amount for each customer?
- A. Join
- B. Union
- C. Group By
- D. Explode
Answer: C
Explanation:
Comprehensive and Detailed Explanation From Exact Extract:
In Workday Prism Analytics, calculating the total purchase amount for each customer requires aggregating data by customer ID. According to the official Workday Prism Analytics study path documents, the appropriate transformation stage for this task is a Group By stage (option C). The Group By stage allows you to group the dataset by a specific field (e.g., customer ID) and apply aggregation functions, such as SUM, to calculate the total purchase amount for each customer. For example, you would group by customer ID and use SUM(purchase_amount) to compute the total. This stage reduces the dataset to one row per customer, with the aggregated total purchase amount, enabling the desired analysis over the entire period.
The other options are incorrect:
* A. Join: A Join stage combines data from two datasets based on a matching condition, but it does not aggregate data to calculate totals.
* B. Union: A Union stage appends rows from one dataset to another, which does not help with calculating totals per customer.
* D. Explode: An Explode stage transforms multi-instance fields into multiple rows, which is unrelated to aggregating purchase amounts.
The Group By stage is the correct choice to aggregate purchase amounts by customer, facilitating the analysis of totals over the entire period.
References:
Workday Prism Analytics Study Path Documents, Section: Data Prep and Transformation, Topic:
Aggregating Data with Group By Stages
Workday Prism Analytics Training Guide, Module: Data Prep and Transformation, Subtopic: Using Group By for Summarization
NEW QUESTION # 30
The Prism use case is to classify workers based on their pay. You must create a field that evaluates worker pay and returns a value that represents various pay ranges. How would you add this field for inclusion on the Prism data source?
- A. Create a derived dataset and build a CASE calculated field to classify workers against their pay.
- B. Build a CASE calculated field function on the TBL directly to ease later transformation.
- C. Build an Evaluate Expression calculated field on your final Prism business object to evaluate workers against their pay.
- D. Add the additional field to your raw data before you ingest into Prism.
Answer: A
Explanation:
Comprehensive and Detailed Explanation From Exact Extract:
In Workday Prism Analytics, classifying workers into pay ranges based on their pay requires creating a new field that evaluates the pay values and assigns them to defined ranges (e.g., "Low," "Medium," "High").
According to the official Workday Prism Analytics study path documents, the recommended approach is to create a derived dataset (DDS) and build a CASE calculated field to classify workers against their pay (option B). The CASE function in a calculated field allows users to define conditional logic (e.g., CASE WHEN pay
< 50000 THEN "Low" WHEN pay < 100000 THEN "Medium" ELSE "High" END), which is ideal for creating pay range classifications. This calculated field is added within a deriveddataset, which can then be published as a Prism data source, making the new field available for reporting and analytics.
The other options are not optimal:
* A. Add the additional field to your raw data before you ingest into Prism: Modifying raw data outside Prism is unnecessary and less flexible, as Prism's transformation capabilities (like CASE) are designed for such tasks.
* C. Build a CASE calculated field function on the TBL directly to ease later transformation: Calculated fields cannot be created directly on a table (TBL) in Prism Analytics; they must be defined in a derived dataset.
* D. Build an Evaluate Expression calculated field on your final Prism business object to evaluate workers against their pay: Prism Analytics does not use "Prism business objects" for calculated fields, and "Evaluate Expression" is not a standard function; this option is not applicable.
Using a CASE calculated field in a derived dataset provides a flexible and maintainable way to classify workers by pay ranges, ensuring the field is included in the final Prism data source.
References:
Workday Prism Analytics Study Path Documents, Section: Data Prep and Transformation, Topic: Creating Calculated Fields with CASE Functions Workday Prism Analytics Training Guide, Module: Data Prep and Transformation, Subtopic: Classifying Data Using Calculated Fields in Derived Datasets
NEW QUESTION # 31
A Prism data administrator combined data from multiple sources down to a final derived dataset, including current worker data. There is a new requirement to append historical worker data to the dataset in a uniform layout. The historical worker data includes some, but not all, fields that align withthe current worker data.
Using current worker data as the primary pipeline, how can the historical worker data points be brought in?
- A. Add a Join stage with an Inner Join.
- B. Add a Join stage with a Right Outer Join.
- C. Add a Union stage.
- D. Add a Join stage with a Left Outer Join.
Answer: C
Explanation:
Comprehensive and Detailed Explanation From Exact Extract:
In Workday Prism Analytics, when the goal is to append data from one dataset to another in a uniform layout, such as combining current worker data with historical worker data, a Union stage is the appropriate transformation. According to the official Workday Prism Analytics study path documents, a Union stage is used to append rows from one pipeline to another, stacking the data vertically while aligning fields based on their names and types. In this scenario, the current worker data (primary pipeline) and historical worker data (secondary pipeline) share some fields, and a Union stage will combine the rows from both datasets into a single dataset. Fields that exist in one pipeline but not the other will have NULL values for the rows where they are not present, ensuring a uniform layout without losing data.
The other options are not suitable for this requirement:
* A. Add a Join stage with a Right Outer Join: A Right Outer Join would include all rows from the historical worker data and only matching rows from the current worker data, which does not align with the goal of appending all data in a uniform layout.
* C. Add a Join stage with a Left Outer Join: A Left Outer Join would include all rows from the current worker data and matching rows from the historical worker data, but this is not an append operation; it's a matching operation based on a join condition, which isn't specified here.
* D. Add a Join stage with an Inner Join: An Inner Join would only include rows where matches exist between the two datasets, potentially excluding non-matching historical or current worker data, which does not meet the requirement to append all data.
The Union stage is the correct approach to append historical worker data to the current worker data, ensuring all rows are included in a uniform layout, with NULLs filling in for missing fields.
References:
Workday Prism Analytics Study Path Documents, Section: Data Prep and Transformation, Topic: Using Union Stages to Append Data in Prism Analytics Workday Prism Analytics Training Guide, Module: Data Prep and Transformation, Subtopic: Combining Datasets with Union Operations
NEW QUESTION # 32
You want to apply a Filter stage to your derived dataset to show only expense reports submitted in the current month and where the expense report total amount is higher than 2000 USD. What should you do?
- A. Use a simple filter, three conditions, and "If All" operator.
- B. Use a simple filter, three conditions, and "If Any" operator.
- C. Use a simple filter, two conditions, and "If All" operator.
- D. Use a simple filter, two conditions, and "If Any" operator.
Answer: C
Explanation:
Comprehensive and Detailed Explanation From Exact Extract:
In Workday Prism Analytics, a Filter stage in a derived dataset is used to include only rows that meet specific criteria. The requirement here is to show expense reports that satisfy two conditions: (1) submitted in the current month, and (2) total amount higher than 2000 USD. According to the official Workday Prism Analytics study path documents, this can be achieved by using a simple filter with two conditions and the "If All" operator (option A).
The first condition would check the submission date, using a function like MONTH() to compare with the current month (e.g., MONTH(submission_date) = MONTH(CURRENT_DATE())). The second condition would compare the total amount (e.g., total_amount > 2000). The "If All" operator ensures that both conditions must be true for a row to be included, which aligns with the requirement that both criteria (current month AND amount > 2000 USD) must be met. A simple filter is sufficient because the logic involves straightforward comparisons without nested conditions.
The other options are incorrect:
* B. Use a simple filter, two conditions, and "If Any" operator: The "If Any" operator would include rows where either condition is true (e.g., submitted in the current month OR amount > 2000 USD), which does not meet the requirement for both conditions to be true.
* C. Use a simple filter, three conditions, and "If All" operator: Only two conditions are needed (submission month and amount), so three conditions are unnecessary.
* D. Use a simple filter, three conditions, and "If Any" operator: This combines the issues of option B (wrong operator) and option C (too many conditions).
Using a simple filter with two conditions and the "If All" operator ensures the dataset includes only the expense reports that meet both criteria.
References:
Workday Prism Analytics Study Path Documents, Section: Data Prep and Transformation, Topic: Applying Filters in Derived Datasets Workday Prism Analytics Training Guide, Module: Data Prep and Transformation, Subtopic: Configuring Simple Filters with Multiple Conditions
NEW QUESTION # 33
A Prism data writer has to create an intermediary Prism calculated field A, used only to achieve a final result in Prism calculated field B and they only need to publish out field B. What should they do?
- A. Add a Manage Fields stage to the DDS and hide field B.
- B. Mark field A as intermediate calculation.
- C. Delete field A from their DDS and just leave field B.
- D. Add a Manage Fields stage to the DDS and hide field A.
Answer: D
Explanation:
Comprehensive and Detailed Explanation From Exact Extract:
In Workday Prism Analytics, when a data writer creates an intermediary calculated field (e.g., field A) solely to derive a final calculated field (e.g., field B) in a Derived Dataset (DDS), they may want to exclude the intermediary field from the published output to keep the dataset clean and focused. According to the official Workday Prism Analytics study path documents, the recommended approach is to add a Manage Fields stage to the DDS and hide field A. The Manage Fields stage allows users to control the visibility of fields in the dataset, enabling them to hide fields that are not needed in the final output while retaining their calculations for internal use within the dataset's transformation logic. By hiding field A, field B can still leverage field A's calculations, and only field B will be visible in the published dataset or data source.
The other options are not suitable:
A: Mark field A as intermediate calculation: There is no specific feature in Prism Analytics to "mark" a field as an intermediate calculation; this is not a supported action.
C: Add a Manage Fields stage to the DDS and hide field B: Hiding field B would defeat the purpose, as field B is the intended output to be published.
D: Delete field A from their DDS and just leave field B: Deleting field A would break the calculation of field B, as field B depends on field A, making this option infeasible.
Using the Manage Fields stage to hide field A ensures that the dataset remains functional while presenting only the necessary fields in the final output, aligning with best practices for data transformation and publishing.
References:
Workday Prism Analytics Study Path Documents, Section: Data Prep and Transformation, Topic: Managing Fields in Derived Datasets Workday Prism Analytics Training Guide, Module: Data Prep and Transformation, Subtopic: Configuring Field Visibility in Datasets
NEW QUESTION # 34
You just imported your table on worker compensation into a derived dataset but before adding any transformation you want to make sure you have no NULL values for the Worker ID field. How can you get this insight?
- A. Add a Manage Fields stage.
- B. Create a Prism calculated field.
- C. Click on the field name and check the stage statistics.
- D. Join on the Worker ID field.
Answer: C
Explanation:
Comprehensive and Detailed Explanation From Exact Extract:
In Workday Prism Analytics, after importing a table into a derived dataset (DDS), you can inspect the data for quality issues, such as NULL values, before proceeding with transformations. According to the official Workday Prism Analytics study path documents, to check for NULL values in a specific field like Worker ID, the most direct method is to click on the field name and check the stage statistics. When viewing a dataset in the Prism Analytics interface, clicking on a field name (e.g., Worker ID) in the dataset preview displays stage statistics, which include metrics such as the count of NULL values, distinct values, and other data quality indicators. This feature allows users to quickly assess the presence of NULLs without modifying the dataset or adding unnecessary stages.
The other options are not the best approach for this task:
* A. Add a Manage Fields stage: The Manage Fields stage is used to modify field properties (e.g., type, visibility), not to inspect data for NULL values.
* C. Create a Prism calculated field: While a calculated field could be used to flag NULLs (e.g., using ISNULL), this is an indirect and unnecessary step compared to checking stage statistics.
* D. Join on the Worker ID field: Joining with another dataset does not help identify NULL values in the Worker ID field and is irrelevant to this task.
Using stage statistics by clicking on the field name provides a straightforward and efficient way to gain insight into NULL values in the Worker ID field.
References:
Workday Prism Analytics Study Path Documents, Section: Data Prep and Transformation, Topic: Data Quality Checks in Derived Datasets Workday Prism Analytics Training Guide, Module: Data Prep and Transformation, Subtopic: Inspecting Data Using Stage Statistics
NEW QUESTION # 35
A Prism data administrator notices that several of the Prism calculated fields on their lineage are producing nil results, so they need to revise the expressions for all of the affected calculated fields. Where can they review the expressions in bulk?
- A. The table or dataset where the calculated field was created.
- B. The View Dataset Lineage report.
- C. Any table in the lineage.
- D. Any dataset in the lineage.
Answer: B
Explanation:
Comprehensive and Detailed Explanation From Exact Extract:
In Workday Prism Analytics, calculated fields are defined within datasets, and their expressions dictate the logic used to compute their values. When issues like nil results arise, an administrator needs a centralized view to review and troubleshoot these expressions. According to the official Workday Prism Analytics study path documents, the View Dataset Lineage report is the tool that allows users to review the lineage of datasets, including the expressions of calculated fields, in bulk. This report provides a visual representation of the data lineage, showing the relationships between tables, datasets, and calculated fields, and allows users to drill into the details of each dataset to inspect the expressions of calculated fields across the lineage.
The other options are not as effective for this purpose:
A: The table or dataset where the calculated field was created: While you can review expressions in the specific dataset where a calculated field was created, this approach does not allow for a bulk review across multiple datasets in the lineage.
C: Any table in the lineage: Tables store raw data and do not contain calculated field expressions, which are defined in datasets.
D: Any dataset in the lineage: Reviewing datasets individually does not provide a bulk view of all calculated fields across the lineage, making it less efficient than the View Dataset Lineage report.
The View Dataset Lineage report is the most efficient way to review and troubleshoot calculated field expressions in bulk, enabling the administrator to identify and revise the problematic expressions causing nil results.
References:
Workday Prism Analytics Study Path Documents, Section: Datasets and Data Sources, Topic: Using View Dataset Lineage for Troubleshooting Workday Prism Analytics Training Guide, Module: Datasets and Data Sources, Subtopic: Managing Calculated Fields in Data Lineage
NEW QUESTION # 36
You have two tables. One with employee data from Workday and another with learner data from an external system. Both tables have an Employee ID field.
In the Employee Data TBL, Employee ID is text.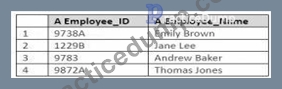
In the Learner Data TBL, Employee ID is numeric.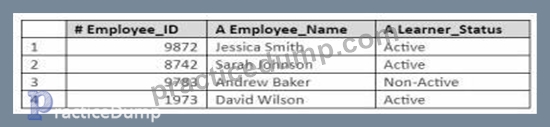
How can you prepare to join these tables, without the potential loss of data?
- A. Import the Learner Data TBL into a DDS and change the field type of Employee ID from numeric to text using a Manage Fields stage.
- B. Import the Employee Data TBL into a DDS and change the field type of Employee ID from text to numeric using a Manage Fields stage.
- C. Change the field type of Employee ID directly on the Learner Data TBL from Numeric to Text.
- D. Change the field type of Employee ID directly on the Employee Data TBL from text to numeric.
Answer: A
Explanation:
In Workday Prism Analytics, joining two tables requires that the fields used in the join condition have compatible data types to avoid data mismatches or loss. The Employee Data TBL has an Employee ID field as text, while the Learner Data TBL has an Employee ID field as numeric. According to the official Workday Prism Analytics study path documents, to join these tables without potential data loss, the best approach is to convert the numeric Employee ID in the Learner Data TBL to text, as text fields can safely store numeric values as strings, but converting text to numeric risks data loss if the text field contains non-numeric characters (e.g., leading zeros or special characters).
The correct method is to import the Learner Data TBL into a Derived Dataset (DDS) and use a Manage Fields stage to change the field type of Employee ID from numeric to text (option D). This ensures that the Employee ID field in both tables is text, enabling a safe and accurate join without losing data. The Manage Fields stage in a DDS allows for field type transformations, which is the recommended approach for preparing data for joins in Prism Analytics.
The other options are less suitable:
* A. Import the Employee Data TBL into a DDS and change the field type of Employee ID from text to numeric using a Manage Fields stage: Converting text to numeric risks data loss if the text field contains non-numeric values, which could lead to errors or missing records during the join.
* B. Change the field type of Employee ID directly on the Employee Data TBL from text to numeric:
Direct field type changes on tables are not supported in Prism Analytics, and even if possible, this approach risks data loss for the same reason as option A.
* C. Change the field type of Employee ID directly on the Learner Data TBL from Numeric to Text:
Direct field type changes on tables are not supported; field type transformations must be done in a DDS using a Manage Fields stage.
By converting the numeric Employee ID to text in a DDS, the join can be performed safely, preserving all data from both tables.
References:
Workday Prism Analytics Study Path Documents, Section: Data Prep and Transformation, Topic: Preparing Data for Joins in Prism Analytics Workday Prism Analytics Training Guide, Module: Data Prep and Transformation, Subtopic: Field Type Transformations Using Manage Fields Stage
NEW QUESTION # 37
While viewing your lineage, you realize you have forgotten to add a description to some of your derived datasets. From the lineage, you double-click on a dataset to view the dataset details. What is the next step to add the missing descriptions?
- A. Select the pencil icon next to the dataset name and Edit Transformations.
- B. Select the pencil icon next to the Import stage to update the description.
- C. Select Related Actions next to the dataset name and Edit Transformations.
- D. Select Add Field from the dataset details to create a description.
Answer: C
Explanation:
To add or update the description of a derived dataset in Workday Prism Analytics, you should access the Edit Dataset Transformations task. This can be done by selecting the Related Actions next to the dataset name and choosing Edit Transformations. This method allows you to modify various aspects of the dataset, including its description.
This process is outlined in the Workday Prism Analytics User Guide, which states:
"If you have permission to edit a dataset, you can access the Edit Dataset Transformations task using these methods:
* Right-click the dataset name on the Data Catalog report and select Edit Transformations.
* Select Edit Transformations from the Quick Actions on the View Dataset Details report.
* Access the Edit Dataset task and select the dataset name that you want to edit." Once in the Edit Dataset Transformations task, you can update the dataset's description by clicking on the configuration icon (often represented as a gear or pencil icon) and editing the description field.
Reference: Workday Prism Analytics User Guide, "Concept: Dataset Workspace" section
NEW QUESTION # 38
You are a new Prism customer and you want to ensure the correct set of fields is brought into a derived dataset. When should you apply a Manage Fields stage?
- A. After the dataset is published.
- B. At the beginning of the Primary Pipeline of the derived dataset.
- C. At the beginning of the primary pipeline of the Base Dataset.
- D. At the end of the Primary Pipeline of a published dataset.
Answer: B
Explanation:
Comprehensive and Detailed Explanation From Exact Extract:
In Workday Prism Analytics, a Manage Fields stage is used to control the fields in a dataset by renaming, hiding, or changing field types, among other actions. According to the official Workday Prism Analytics study path documents, to ensure the correct set of fields is brought into a derived dataset (DDS), the Manage Fields stage should be applied at the beginning of the Primary Pipeline of the derived dataset (option C).
Placing the Manage Fields stage early in the pipeline-right after the initial import stage (Stage 1)-allows you to define the field structure upfront, ensuring that subsequent transformationstages (e.g., Join, Filter, Calculate Field) operate on the desired set of fields. This approach helps maintain consistency and avoids unnecessary processing of fields that are not needed in later stages.
The other options are not optimal:
* A. After the dataset is published: You cannot add transformation stages like Manage Fields after a dataset is published; transformations must be applied during the dataset's creation or editing.
* B. At the end of the Primary Pipeline of a published dataset: Similar to option A, you cannot modify a published dataset's pipeline, and placing Manage Fields at the end would not prevent unnecessary fields from being processed in earlier stages.
* D. At the beginning of the primary pipeline of the Base Dataset: A Base Dataset does not have a transformation pipeline; it is a direct import of a table, so Manage Fields stages can only be applied in a Derived Dataset.
Applying the Manage Fields stage at the beginning of the derived dataset's Primary Pipeline ensures efficient data preparation and transformation.
References:
Workday Prism Analytics Study Path Documents, Section: Data Prep and Transformation, Topic: Using Manage Fields in Derived Datasets Workday Prism Analytics Training Guide, Module: Data Prep and Transformation, Subtopic: Best Practices for Field Management in Pipelines
NEW QUESTION # 39
You have a number of Workday reports that use a Prism data source. When are the values of the Prism calculated fields in the Workday reports calculated?
- A. At time of publishing.
- B. At dataset creation time.
- C. At the calculated field creation time.
- D. At report run time.
Answer: A
NEW QUESTION # 40
You want to import a Workday custom report into the data catalog. You have already enabled it as a web service and enabled it for Prism Analytics. What other configuration is required?
- A. It must be imported via sFTP.
- B. It must be shared with or owned by the user importing the report.
- C. It must be tagged with a Prism Analytics report tag.
- D. It must be built as a matrix report.
Answer: B
Explanation:
Comprehensive and Detailed Explanation From Exact Extract:
To import a Workday custom report into the Prism Analytics Data Catalog, specific configurations are required to ensure the report is accessible and usable. According to the official Workday Prism Analytics study path documents, in addition to enabling the report as a web service and enabling it for Prism Analytics, the report must be shared with or owned by the user who is performing the import. This security requirement ensures that only authorized users can access and import the report into the Data Catalog, aligning with Workday's configurable security model. The user must either be the owner of the report or have it shared with them through appropriate security permissions (e.g., via a security group or direct sharing).
The other options are incorrect:
* A. It must be imported via sFTP: Custom reports are imported directly through Workday's web service integration, not via sFTP, which is typically used for file-based data sources.
* B. It must be built as a matrix report: There is no requirement for the report to be a matrix report; Prism Analytics supports various report types, including advanced and simple reports, as long as they are properly configured.
* D. It must be tagged with a Prism Analytics report tag: Tagging is not a mandatory step for importing a report into the Data Catalog, though it may be used for organizational purposes.
Ensuring that the report is shared with or owned by the importing user is a critical step to maintain security and governance during the integration process.
References:
Workday Prism Analytics Study Path Documents, Section: Integrating Prism with Workday Reports, Topic:
Importing Custom Reports into the Data Catalog
Workday Prism Analytics Training Guide, Module: Datasets and Data Sources, Subtopic: Security Requirements for Report Integration
NEW QUESTION # 41
What task or report should you access to view a Prism data source?
- A. View Dataset Details report
- B. Edit Dataset Transformations task
- C. View Prism Data Source report
- D. Edit Data Source Security task
Answer: C
Explanation:
Comprehensive and Detailed Explanation From Exact Extract:
In Workday Prism Analytics, a Prism data source represents the published dataset that is available for reporting and analytics within the Workday ecosystem. According to the official Workday Prism Analytics study path documents, the "View Prism Data Source" report is the specific task or report designed to allow users to view the details of a Prism data source. This report provides comprehensive information about the data source, including its metadata, structure, and associated attributes, enabling users to understand the data available for reporting purposes.
The other options do not serve this purpose. The "Edit Dataset Transformations task" is used to modify the transformation logic applied to a dataset, not to view a data source. The "Edit Data Source Security task" focuses on managing security settings for a data source, such as access permissions, rather than viewing its contents. Similarly, the "View Dataset Details report" provides information about a dataset (including its metadata and sample rows) but does not specifically address the published Prism data source, which is a distinct entity created after a dataset is published.
The "View Prism Data Source" report is the correct choice as it directly aligns with the need to inspect the properties and structure of a Prism data source, ensuring users can verify its suitability for reporting or integration with Workday reports.
References:
Workday Prism Analytics Study Path Documents, Section: Datasets and Data Sources, Topic: Managing and Viewing Prism Data Sources Workday Prism Analytics Training Guide, Module: Publishing and Visualizing Data, Subtopic: Viewing and Validating Data Sources
NEW QUESTION # 42
What report can you run to edit and maintain your Prism import and publish schedules?
- A. Prism Activities Monitor
- B. Prism Management Console
- C. Prism Usage
- D. Scheduled Future Processes
Answer: D
Explanation:
Comprehensive and Detailed Explanation From Exact Extract:
In Workday Prism Analytics, managing schedules for importing data into tables or publishing datasets as Prism data sources is a key administrative task. According to the official Workday Prism Analytics study path documents, the Scheduled Future Processes report (option A) is the tool used to edit and maintain Prism import and publish schedules. This report provides a centralized view of all scheduled processes in Workday, including Prism-related tasks such as Data Change tasks (for imports) and dataset publish schedules. Users can access this report to view, edit, or cancel scheduled processes, ensuring that data imports and publishes occur at the desired frequency and time.
The other options are incorrect:
* B. Prism Management Console: The Prism Management Console provides an overview of Prism activities and resources but does not allow for editing or maintaining schedules.
* C. Prism Activities Monitor: This report monitors the status of Prism activities (e.g., running or completed tasks) but does not manage schedules.
* D. Prism Usage: The Prism Usage report tracks usage metrics for Prism Analytics but does not handle scheduling tasks.
The Scheduled Future Processes report is the correct tool for managing Prism import and publish schedules, ensuring efficient data updates.
References:
Workday Prism Analytics Study Path Documents, Section: Publishing and Visualizing Data, Topic: Managing Import and Publish Schedules Workday Prism Analytics Training Guide, Module: Publishing and Visualizing Data, Subtopic: Using Scheduled Future Processes for Prism Tasks
NEW QUESTION # 43
When using a window function to calculate averages in Prism, what field type must the function operate on?
- A. Text
- B. Boolean
- C. Date
- D. Numeric
Answer: D
Explanation:
Comprehensive and Detailed Explanation From Exact Extract:
In Workday Prism Analytics, window functions are used to perform calculations across a set of rows, such as calculating averages with a function like AVG. According to the official Workday Prism Analytics study path documents, the AVG window function, which computes the average, must operate on a fieldof type Numeric.
This is because averaging requires numerical values to perform arithmetic operations (e.g., summing the values and dividing by the count of rows). Non-numeric field types, such as Text or Date, cannot be averaged, and Boolean fields (true/false) are not suitable for this type of calculation. For example, a window function like AVG(salary) OVER (PARTITION BY department) would calculate the average salary per department, where "salary" must be a Numeric field.
The other options are incorrect:
* A. Text: Text fields cannot be used for arithmetic operations like averaging.
* B. Boolean: Boolean fields (true/false) are not suitable for calculating averages.
* D. Date: Date fields cannot be directly averaged; they require conversion to a numeric representation (e.
g., days since a reference date) first.
The requirement for a Numeric field type ensures that the AVG window function can perform the necessary mathematical computations accurately.
References:
Workday Prism Analytics Study Path Documents, Section: Data Prep and Transformation, Topic: Window Functions and Field Type Requirements Workday Prism Analytics Training Guide, Module: Data Prep and Transformation, Subtopic: Using AVG in Window Functions
NEW QUESTION # 44
You want to remove data within a Prism data source without deleting any dependent custom reports. What task can you use to do this?
- A. Unpublish Dataset
- B. Inactivate Dataset
- C. Delete Dataset
- D. Delete Published Rows
Answer: D
Explanation:
Comprehensive and Detailed Explanation From Exact Extract:
In Workday Prism Analytics, removing data from a Prism data source (PDS) without affecting dependent custom reports requires a careful approach to preserve the data source's structure and dependencies.
According to the official Workday Prism Analytics study path documents, the task to use is Delete Published Rows (option D). This task removes the data rows within the Prism data source while keeping the data source' s metadata (e.g., field definitions) and structure intact. Since custom reports depend on the data source's structure rather than the specific data rows, deleting the published rows will not break the reports. After deleting the rows, you can republish the dataset with updated data, and the reports will continue to function with the new data, assuming the structure remains unchanged.
The other options are incorrect:
* A. Inactivate Dataset: Inactivating a dataset disables it but does not remove data from the published data source, and it may still affect reports by making the data source inaccessible.
* B. Delete Dataset: Deleting the dataset entirely will also delete the Prism data source, breaking any dependent custom reports.
* C. Unpublish Dataset: Unpublishing the dataset removes the Prism data source, which will break dependent reports until the dataset is republished.
The Delete Published Rows task ensures that data is removed from the Prism data source without impacting the dependent custom reports, allowing for seamless data updates.
References:
Workday Prism Analytics Study Path Documents, Section: Publishing and Visualizing Data, Topic: Managing Data in Prism Data Sources Workday Prism Analytics Training Guide, Module: Publishing and Visualizing Data, Subtopic: Removing Data Without Breaking Report Dependencies
NEW QUESTION # 45
The final derived dataset in a Prism pipeline is complete and ready to publish. What should be done prior to publishing?
- A. Edit the Dataset API Name to reflect in the name of the Prism data source.
- B. Create a derived dataset with the PDS suffix.
- C. Add a Group By stage to the final derived dataset to add summary calculations.
- D. Create a table without the Enable for Analysis checkbox selected.
Answer: A
Explanation:
Comprehensive and Detailed Explanation From Exact Extract:
In Workday Prism Analytics, before publishing a derived dataset as a Prism data source (PDS), it's important to ensure that the dataset is properly configured for downstream use. According to the official Workday Prism Analytics study path documents, one key step to take prior to publishing is to edit the Dataset API Name to reflect in the name of the Prism data source (option D). The Dataset API Name determines the name of the published Prism data source, which is used in reporting, discovery boards, and integrations. Setting a meaningful and descriptive API name (e.g., "Expense_Reports_by_Location") ensures that the data source is easily identifiable and aligns with naming conventions, improving usability and manageability in the Workday ecosystem. This step is a best practice to avoid confusion and ensure clarity for report writers and analysts.
The other options are not required or relevant:
* A. Add a Group By stage to the final derived dataset to add summary calculations: Adding a Group By stage is not mandatory unless the use case specifically requires summarizations, which is not indicated here.
* B. Create a table without the Enable for Analysis checkbox selected: Creating a new table is unnecessary, as the dataset is already complete, and the "Enable for Analysis" checkbox is relevant for real-time updates, not a requirement for publishing a derived dataset.
* C. Create a derived dataset with the PDS suffix: Creating a new dataset is not needed, as the final derived dataset is already prepared, and adding a "PDS" suffix is not a required step for publishing.
Editing the Dataset API Name ensures the Prism data source has a clear and meaningful name, facilitating its use in reporting and analytics.
References:
Workday Prism Analytics Study Path Documents, Section: Publishing and Visualizing Data, Topic: Best Practices for Publishing Prism Data Sources Workday Prism Analytics Training Guide, Module: Publishing and Visualizing Data, Subtopic: Configuring Dataset API Names Before Publishing
NEW QUESTION # 46
You want to delete a Prism data source, but you are unable to complete the dataset unpublish. You have deleted the Report Writer reports. What else must you delete, if present?
- A. Discovery board visualizations
- B. Upstream datasets
- C. Published rows
- D. Upstream tables
Answer: A
Explanation:
Comprehensive and Detailed Explanation From Exact Extract:
In Workday Prism Analytics, unpublishing a dataset to delete a Prism data source requires removing all dependencies that reference the data source. According to the official Workday Prism Analytics study path documents, if you have already deleted Report Writer reports but are still unable to unpublish the dataset, you must also delete any discovery board visualizations that reference the Prism data source (option C). Discovery boards in Workday allow users to create visualizations based on Prism data sources, and these visualizations create a dependency on the data source. If such visualizations exist, the system prevents the dataset from being unpublished until they are removed, ensuring that no downstream dependencies are broken.
The other options are incorrect:
* A. Upstream tables: Upstream tables are the source of data for the dataset, but they are not dependencies of the published data source and do not need to be deleted to unpublish the dataset.
* B. Published rows: Published rows are part of the data source itself and are removed when the dataset is unpublished; they are not a separate dependency to delete.
* D. Upstream datasets: Upstream datasets may feed into the dataset being unpublished, but they are not dependencies of the published data source and do not prevent unpublishing.
Deleting discovery board visualizations ensures all dependencies are cleared, allowing the dataset to be unpublished and the Prism data source to be deleted.
References:
Workday Prism Analytics Study Path Documents, Section: Publishing and Visualizing Data, Topic:
Unpublishing Prism Data Sources
Workday Prism Analytics Training Guide, Module: Publishing and Visualizing Data, Subtopic: Managing Dependencies for Data Source Deletion
NEW QUESTION # 47
A report that uses a Prism data source that you created has a brand new requirement that Expense Partner by Location should only see expense reports for workers for the locations they support. Given that you have the Location Hierarchy (instance) field in your dataset used for publishing, how can you adjust to meet the requirement?
- A. Run the Edit Data Source Security task to update row-level security and then republish the PDS.
- B. Run the Edit Data Source Security task to update the Securing Entities.
- C. Run the Edit Data Source Security task to update row-level security.
- D. Run the Edit Data Source Security task to update the Securing Entities and then republish the PDS.
Answer: A
Explanation:
Comprehensive and Detailed Explanation From Exact Extract:
In Workday Prism Analytics, restricting access to specific rows in a Prism data source (PDS) based on afield like Location Hierarchy for users such as Expense Partners requires implementing row-level security.
According to the official Workday Prism Analytics study path documents, to meet the requirement that Expense Partners only see expense reports for the locations they support, you should run the Edit Data Source Security task to update row-level security and then republish the PDS (option B).
The Location Hierarchy (instance) field in the dataset can be used to define row-level security rules, ensuring that each Expense Partner only sees data for their assigned locations. The Edit Data Source Security task allows you to configure row-level security by mapping the Location Hierarchy field to the user's security profile (e.g., their assigned locations). After updating the security settings, republishing the Prism data source is necessary to apply the changes, ensuring the updated security rules take effect in the reports that use the data source.
The other options are incorrect:
* A. Run the Edit Data Source Security task to update the Securing Entities and then republish the PDS:
Securing Entities are used to control overall access to the data source (e.g., via security domains), not to restrict data at the row level based on a field like Location Hierarchy.
* C. Run the Edit Data Source Security task to update row-level security: While updating row-level security is correct, the changes will not take effect in reports until the data source is republished, making this option incomplete.
* D. Run the Edit Data Source Security task to update the Securing Entities: As with option A, updating Securing Entities does not address row-level security for location-based restrictions.
Updating row-level security and republishing the PDS ensures that Expense Partners only see the relevant expense reports, meeting the requirement while maintaining security governance.
References:
Workday Prism Analytics Study Path Documents, Section: Security and Governance in Prism, Topic:
Implementing Row-Level Security in Prism Data Sources
Workday Prism Analytics Training Guide, Module: Security and Governance in Prism, Subtopic: Configuring Row-Level Security for Location-Based Access
NEW QUESTION # 48
When joining datasets, what items must match?
- A. The number of rows in each dataset.
- B. The field types for the Match Row fields.
- C. The field names for the Match Row fields.
- D. The level of detail in each dataset.
Answer: B
Explanation:
Comprehensive and Detailed Explanation From Exact Extract:
In Workday Prism Analytics, joining datasets requires that the fields used in the join condition (Match Row fields) are compatible to ensure accurate matching. According to the official Workday Prism Analytics study path documents, the field types for the Match Row fields must match (option A). For example, if the join condition is based on an Employee ID field, the field type (e.g., Text or Numeric) must be the same in both datasets. Mismatched field types (e.g., Text in one dataset and Numeric in another) can lead to join failures or incorrect results, as Prism cannot reliably compare values of different types. This often requires using a Manage Fields stage to align field types before the join.
The other options are incorrect:
* B. The number of rows in each dataset: The number of rows does not need to match; joins can handle datasets of different sizes, depending on the join type (e.g., Left Outer Join).
* C. The level of detail in each dataset: The level of detail (granularity) does not need to match; joins can combine datasets with different levels of detail as long as the Match Row fields are compatible.
* D. The field names for the Match Row fields: The field names do not need to be identical; the join condition maps fields between datasets, so different names can be used as long as the types and values are compatible.
Ensuring that the field types of the Match Row fields are the same is critical for a successful join operation in Prism Analytics.
References:
Workday Prism Analytics Study Path Documents, Section: Data Prep and Transformation, Topic:
Requirements for Joining Datasets in Prism Analytics
Workday Prism Analytics Training Guide, Module: Data Prep and Transformation, Subtopic: Configuring Join Conditions for Datasets
NEW QUESTION # 49
A Prism data administrator needs to add an Explode stage to a derived dataset to create a new single-instance type field. What is the only field type you can select in the Explode stage?
- A. Text
- B. Numeric
- C. Single-Instance
- D. Multi-Instance
Answer: D
Explanation:
Comprehensive and Detailed Explanation From Exact Extract:
In Workday Prism Analytics, an Explode stage is used in a derived dataset to transform a multi-instance field into multiple rows, effectively creating single-instance fields for each instance. According to the official Workday Prism Analytics study path documents, the only field type you can select in the Explode stage is Multi-Instance (option B). A multi-instance field, often sourced from Workday data, contains multiple values for a single record (e.g., a list of certifications for a worker). The Explode stage "explodes" this field into separate rows, one for each instance, while converting the multi-instance fieldinto a single-instance field in the output. For example, if a worker has three certifications in a multi-instance field, the Explode stage would create three rows, each with a single certification value.
The other options are incorrect:
* A. Numeric: Numeric fields are single-instance by nature and cannot be exploded, as they do not contain multiple values.
* C. Single-Instance: Single-instance fields contain one value per record and cannot be used in an Explode stage, which requires a multi-instance field to operate.
* D. Text: While a Text field can be single or multi-instance, the Explode stage specifically requires a Multi-Instance field, not just any Text field.
The requirement for a Multi-Instance field in the Explode stage ensures that the transformation can properly expand the data into multiple rows as intended.
References:
Workday Prism Analytics Study Path Documents, Section: Data Prep and Transformation, Topic: Using the Explode Stage in Derived Datasets Workday Prism Analytics Training Guide, Module: Data Prep and Transformation, Subtopic: Handling Multi- Instance Fields with Explode Stages
NEW QUESTION # 50
......
Pass Workday Workday-Prism-Analytics exam - questions - convert Tets Engine to PDF: https://pass4sure.practicedump.com/Workday-Prism-Analytics-exam-questions.html